
Taming the Data Entry Parrot: Repeating Forms in Clinical Research · Part 1 of 3
Repeating Study Forms in Clinical Research: When “+ New” Isn’t New
Repeating a form starts with a deceptively simple question: is this actually new? Part 1 looks at how to identify repeated instances, prevent duplicates and conflicts, help people recognize what’s already there, and manage what happens when “+ New” starts something else.
At a glance
First ask whether new really means new
Some repeating forms simply create another independent observation. Others represent things that may already exist and need to be recognized before another instance is created.
Define what makes an instance unique
An identifier may be a single field, a combination of fields, or a relationship to information already collected. An exact duplicate is not the only possible conflict.
Design for both the system and the person
The computer needs information that uniquely identifies an instance. The person entering data needs information that helps them recognize the correct instance.
Plan for what happens when you get it wrong
Creating a duplicate may affect more than one row. If an instance triggers follow-up collection or other related data, correcting the mistake can become much more complicated.
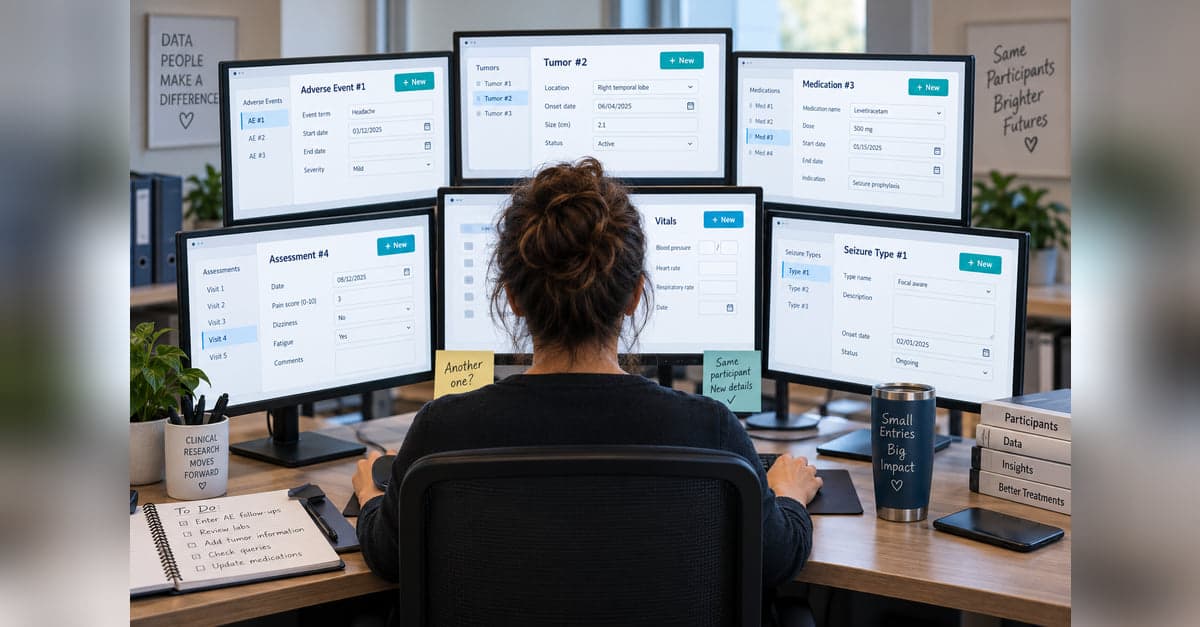
There is a deceptively simple feature on some data-entry forms: + New.
Need to enter another tumor? Click New. Another medication? New. Another adverse event? New. Another assessment? New.
Sometimes that's exactly as simple as it sounds.
When “New” Really Is New
Suppose we're assessing pain, dizziness, lightheadedness, and vertigo several times during a clinic visit. We complete Assessment 1, then later Assessment 2 and Assessment 3. Each assessment is independent. Nothing from Assessment 1 carries forward into Assessment 2, and the values entered previously don't constrain what can be entered next.
Every time we click + New, we get a blank form and make another observation. We might limit how many assessments can be created, but beyond that there may be very little for the system to figure out. + New really does just mean new.
Data Entry Déjà Vu
Now suppose the repeating form represents a tumor. The participant already has several tumors in the study. You find a tumor in today's source information and reach for + New.
But first: Have I entered this before?
Maybe it's a new tumor. Maybe it's one that's already in the system. Now the problem isn't simply whether we're allowed to repeat the form. We need some way to establish which tumor we're talking about.
What Makes Something New?
Sometimes establishing identity is straightforward. A tumor might be assigned a unique Tumor ID. Seizure types might be identified as A, B, C, and D, with each identifier allowed only once. In database terms, we might use a primary key, one field or a combination of fields that uniquely identifies an instance.
But deciding whether something is new doesn't always reduce to finding an exact duplicate.
Consider medication use. Someone can start and stop the same medication several times. Medication A from January through March, again from June through August, and again from November through December can represent three perfectly legitimate periods of use.
Now suppose the participant already has Medication A, 10 mg, January 1 through June 30, and someone tries to enter Medication A, 20 mg, March 15 through April 30. The start dates are different. The end dates are different. A simple rule looking for an identical Medication + Begin Date + End Date wouldn't find a duplicate.
A duplicate is the same instance entered again.
A conflict is something else: the values are not identical, but the new instance is incompatible with information already present.
But if the way we're representing these data assumes that a participant can't simultaneously be taking two different doses of Medication A, the new entry still isn't allowed. The question isn't just “Have these exact values been entered before?” It becomes “Does what I'm entering conflict with something already here?”
We'll come back to the mechanics of dates and overlapping events in Part 3. The important point here is that deciding whether something is new can require understanding its relationship to what has already been entered.
What If We Don't Know Yet?
An instance can exist before we know enough to fully identify it.
An imaging study may reveal a lesion before its location or classification has been completely characterized. A seizure may have been observed but not yet classified. An adverse event may still be under evaluation. The event is real and we need somewhere to collect information about it, but some of the information we would normally use to distinguish it from other instances isn't available yet.
That creates another opportunity for duplicates. One person creates the unidentified instance today. Someone else encounters it tomorrow and doesn't recognize it as the same thing.
A repeating form therefore has to accommodate two things:
- What eventually distinguishes the instance.
- What happens while that information is still incomplete.
The Computer Has to Know. So Does the Person.
Even when the system has a perfect identifier, the person entering the data still must recognize the correct instance.
Suppose the database identifies a tumor as Tumor 0073. That may work perfectly for the computer, but 0073 may mean very little to the coordinator reading today's clinical note. They may recognize it much more readily as Left frontal lobe, onset 3/12/25.
Those are two different jobs. System identity is the information that lets the database distinguish one instance from another. Human recognition is the information that helps the person recognize the instance in front of them.
There may even be a third job. Task-specific recognition changes with the work. Someone entering clinical information might need location and onset date to recognize the tumor. Someone pulling specimens may care much more about specimen ID and freezer location. It's the same tumor, but the information that helps someone work with it changes with the task.
The rules themselves can also extend beyond a single pair of instances. A study might allow only one primary tumor, for example. Another design might allow only one active dose of a medication at a time. In cases like these, deciding whether another instance can be created requires looking at the collection as a whole. The question becomes “Is this allowed given everything else we've already collected?”
When “New” Starts Something Else
Getting the original instance right becomes even more important when creating it causes other data collection to happen.
Consider adverse events. A mild headache might require weekly follow-up, while a serious adverse event might require daily follow-up. Creating the adverse event therefore does more than add another form. That particular adverse event becomes the anchor for its own data-collection schedule.
The follow-up assessments may themselves be independent observations. Each one might collect symptoms, physical findings, functional status, organ-system findings, or resolution. Those assessments don't establish the identity of the adverse event. They happen because that particular adverse event exists.
Now imagine discovering three days later that AE #3 wasn't new at all. It was the same adverse event as AE #2.
The problem is no longer simply deleting a duplicate row.
- What happens to the follow-up assessments attached to the duplicate?
- Can the two instances be merged?
- Can data be reassigned from one to the other?
- What happens to future scheduled collection?
The same problem can appear in other ways. A tumor gets entered twice. Two differently described events later turn out to be the same event. A procedure gets associated with Tumor 2 when it actually belonged to Tumor 1.
Preventing those mistakes is important. So is deciding how to recover when one gets through.
Before Clicking “New”
At its simplest, a repeating form really can be + New → blank form → another observation. The more useful question is whether that's actually the structure of the data we're collecting.
Before configuring a repeating form, ask:
- Are the instances independent?
- What makes one instance different from another?
- Can the same thing legitimately occur more than once?
- Can an instance exist before everything needed to identify it is known?
- Can a new instance conflict with existing information without being an exact duplicate?
- What helps the person recognize the correct existing instance?
- Does creating an instance cause other data collection to follow?
- What happens when someone creates an instance they shouldn't have?
Put it to work
Identity
Define what makes an instance unique.
Determine which field, combination of fields, or relationships distinguish one instance from another.
Account for incomplete identity.
Decide what happens when an instance needs to exist before all of the information normally used to identify it is available.
Recognition
Show people enough to recognize what already exists.
The database identifier may not be the information a coordinator, clinician, or other user needs to identify the correct instance.
Consider the task.
Different workflows may require different information to recognize and work with the same underlying instance.
Conflicts and recovery
Look beyond exact duplicates.
Define combinations, overlaps, or collection-level rules that can make a new instance invalid even when its values are not identical to an existing one.
Plan for mistakes.
Decide how duplicates can be merged, reassigned, retired, or otherwise corrected, especially when related data collection has already begun.
Before making "+ New" easy to click, decide what "new" actually means.
All parts in this series
Taming the Data Entry Parrot: Repeating Forms in Clinical Research
Sometimes study forms repeat. This three-part series looks at what makes each instance unique, what happens to its data over time, and how repeating forms relate to the rest of the study.
Repeating Study Forms in Clinical Research: When “+ New” Isn’t New
Repeating a form starts with a deceptively simple question: is this actually new? Part 1 looks at how to identify repeated instances, prevent duplicates and conflicts, help people recognize what’s already there, and manage what happens when “+ New” starts something else.
Repeating Study Forms in Clinical Research: What Data Should Carry Forward
When a repeating form comes back, should it start fresh or bring previous data with it? Part 2 looks at what gets carried forward, what stays independent, and when previous information needs to be reviewed or reconciled.
Repeating Study Forms in Clinical Research: How to Keep Instances Straight
Repeating forms can become difficult to manage when the same information appears across visits, dates, and related events. Part 3 looks at how thoughtful layouts and timelines can help people see what already exists, understand how it fits together, and know where new information belongs.
Designing something like this yourself?
Tell us what you are building and we will show you how it maps onto Studytrax.
Get started